
 By
Contents
- No-code AI apps hit a complexity wall because builders hide data, backend, and API limits.
- Diagnose the failing layer first: data, AI calls, generated logic, platform limits, or security.
- Move only the failing layer to PostgreSQL or Supabase, and keep the interface that works.
- Track latency, query time, peak errors, and token cost per transaction to decide what moves.
Key Takeaways
Your no-code AI app cannot scale because builders are made for prototypes, not production load. They hide database, backend, and API limits that break under concurrent users. That is an architecture problem, not just a user-count problem.
None of this means your builder was the wrong choice. No-code tools prove an idea quickly, which makes them a sensible place to start. A validated product outgrows its architecture, and our AI development services team rebuilds thin layers.
The real question is which layer gave out first. This guide covers six causes, a numbered diagnosis, and a failing-layer scorecard. It ends with a choice: patch, hybridize, or rebuild with our MVP development services.
Why No-Code AI Apps Hit the Complexity Wall
A no-code AI app hits the complexity wall when real-world load exposes the layers beneath its interface. Builders such as Lovable, Bolt, Replit, and Bubble optimize for what you see on screen. The data model, backend, and security model get far less attention. Yet those layers decide how the app handles concurrent users.
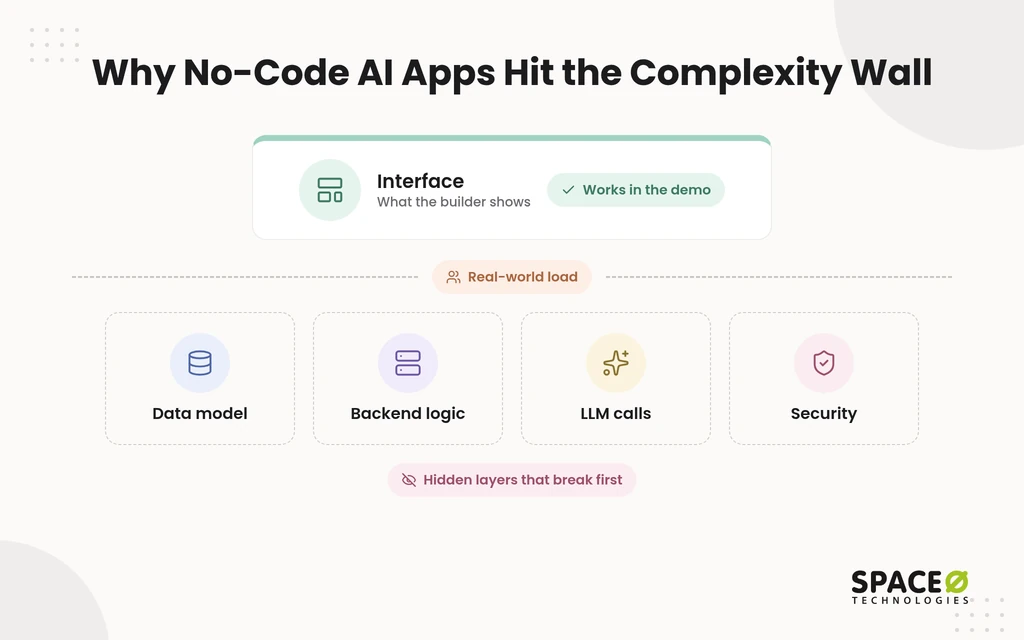
No-code does not remove complexity; it hides it. Vibe-coded apps are tuned for demos, quick wins, and happy paths. Production brings multiple users, edge cases, network drops, and session failures.
Scaling trips up many teams; McKinsey’s State of AI survey found only about one-third scaled AI enterprise-wide.
Six causes show up most often, in this order:
- Missing data and backend architecture: Builders prioritize the visual user interface (UI), so schema, indexing, and server logic stay thin or absent.
- Database and concurrency bottlenecks: Unindexed tables, missing pagination, and no connection pooling turn every new user into extra database load.
- Large language model (LLM) cost, rate limits, and latency: Per-token fees, application programming interface (API) rate limits, and chained model calls compound as users grow.
- Fragile generated logic: Prompt-generated “spaghetti” code ties features together, so each fix quietly breaks another feature.
- Platform limits and vendor lock-in: User and storage caps, pricing tiers, and limited code export tighten with usage, so leaving later can mean rebuilding.
- Security and compliance gaps: Authentication, role-based access control (RBAC), and privilege escalation checks are rarely designed in. Health Insurance Portability and Accountability Act (HIPAA) requirements are often missing too.
Platform caps differ by builder. Our guide to low-code mobile app development platforms compares the tools many teams start on. Each cause lives in a different layer. The next step is finding which one gave out first.
How to Find Which Layer Is Failing
Match the symptom you see to the layer that is failing, then pick the fix that layer needs. Most scaling problems show up as one of five symptoms, and each layer has a different repair cost. Diagnose before you rebuild anything.
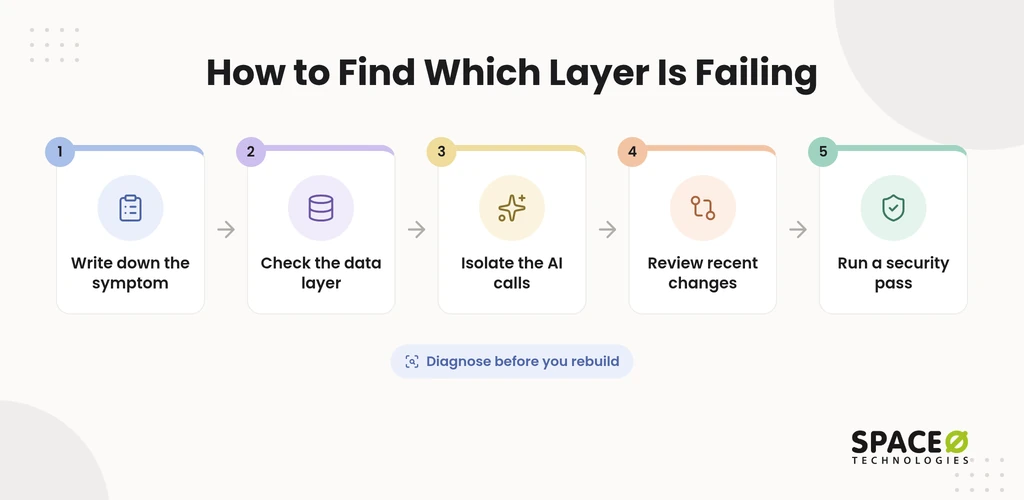
- Write down the symptom: Note what fails, when it fails, and how many users or requests were active.
- Check the data layer first: Compare query times now against when the app held fewer records.
- Isolate the AI calls: Test model-backed features alone and watch for timeouts, rate-limit errors, and token spikes.
- Review recent changes: If new features broke old ones, the generated logic is the failing layer.
- Run a security pass: Confirm roles, tenant data isolation, and audit controls before any compliance review.
| Symptom | Layer that’s failing | Likely cause | Fix path |
|---|---|---|---|
| Pages slow down under concurrent users | Database | Unindexed tables, unplanned relationships, a query fired on every keystroke | Fix in place: add indexes, batch queries, redesign the schema |
| AI features time out or fail during traffic spikes | LLM and API layer | Synchronous model calls, no caching or queues, API rate limits | Decouple: move AI calls to a backend with caching and background jobs |
| The monthly bill climbs faster than revenue | Platform and model pricing | Builder pricing tiers, usage fees, per-token LLM costs | Decouple: cache repeat requests, route simple tasks to smaller models |
| New features break old ones | Generated application logic | Spaghetti AI code with no clear separation of concerns | Decouple or migrate: rebuild core logic as structured backend services |
| The app fails a security or compliance review | Authentication and access control | No RBAC, privilege escalation gaps, missing audit controls | Migrate core services: design auth and access rules from scratch |
The same load patterns apply beyond no-code, as our guide on scaling web applications explains.
Does your platform change which layer fails first?
Yes, your platform sets the hard ceiling because it decides how much code and data you can take. If your builder exports usable code, you can usually decouple the backend and keep the frontend. If it limits export, migration becomes the realistic path. Check your platform’s export terms and plan caps before you choose.
Why do AI features fail first under load?
AI features often fail first because each request waits on a slow, rate-limited, metered model call. One user rarely notices this. Hundreds of simultaneous users hit API rate limits and latency at once.
Chained calls make it worse, because each step waits on the one before it. Every repeated question also costs tokens again. Our LLM integration cost guide shows how that token spend adds up.
Once you know the symptom, you can decide which layer earns the move.
The Failing-Layer Scorecard: What to Move and What to Leave Alone
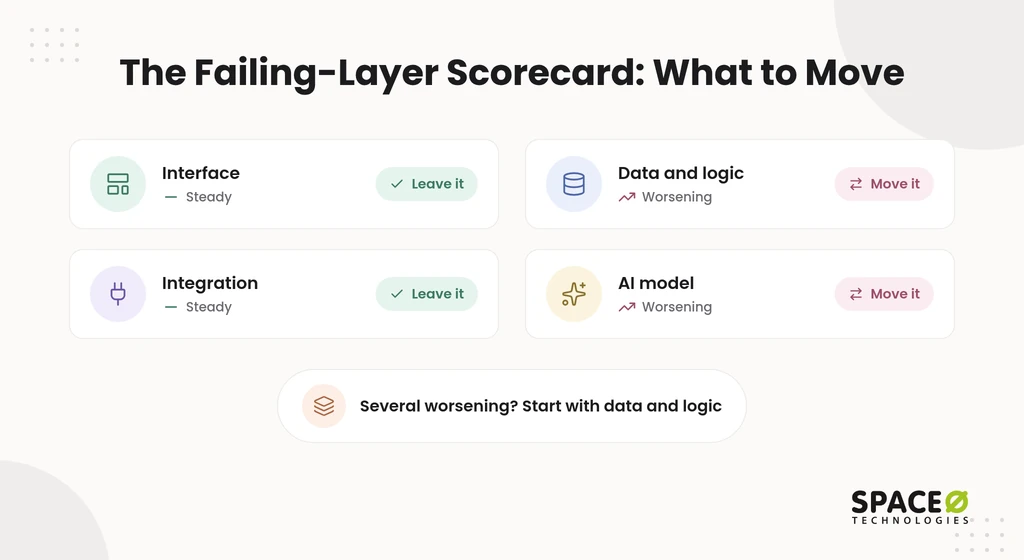
Score each layer by its trend signals, then move only the layer whose signals keep worsening. A layered approach helps you find the constrained layer. This scorecard adds trend signals and a decision rule. It uses direction of movement rather than fixed thresholds, because the right number depends on your app.
Which signals should you track for each layer?
Track a few trend signals per layer, and watch whether each rises as users grow.
| Layer | Trend signals to watch | Move it when | Leave it alone when |
|---|---|---|---|
| Interface (UI and frontend) | Screen interactions stay fast while backend calls slow down | The builder blocks a feature you need or limits code export | Users are satisfied, and slowness traces to another layer |
| Data and logic (database and backend rules) | Query time rises as records grow; 95th- and 99th-percentile (p95 and p99) latency creeps up; errors climb at peak concurrency | Move to PostgreSQL or Supabase with indexes, pagination, and connection pooling | Query times stay flat as data volume grows |
| Integration (APIs, webhooks, and automations) | Failed or retried calls rise at peak; workflows time out more often | Move to backend services with queues and retries | Call volumes are stable, and retries stay rare |
| AI model (LLM calls, prompts, and agents) | Token cost per transaction rises; rate-limit errors appear at peak; accuracy slips after prompt changes | Move calls behind a backend with caching, queues, smaller-model routing, and an evaluation suite | Cost per transaction holds steady and evaluations keep passing |
One signal cuts across every layer: the share of engineering time spent on workarounds. When that share keeps rising, the platform’s hard ceiling is close.
What is the decision rule?
Move the one layer whose signals worsen, and start with data and logic if several do.
- One layer worsening: Move that layer only and leave the rest in place.
- Several layers worsening: Start with data and logic, because the integration and AI layers depend on it.
- Workaround time rising everywhere: Plan a migration of core services outside the builder.
- Interface still working: Leave the frontend alone until a signal says otherwise.
Who benefits most from moving one layer at a time?
Moving one layer suits apps with paying users or regulated data that must stay live. Multi-tenant data and audit obligations raise the stakes further. Those teams cannot afford downtime or a retraining cycle for users. A targeted move protects revenue while the weak layer gets rebuilt.
With the failing layer identified, the fix follows a set order.
How to Fix a No-Code AI App That Cannot Scale
Fix the layers in order: data model, backend, AI quality, team, and migration last. Adding UI features to a weak foundation makes the wall arrive sooner. Most products need only the first two steps, and fewer need a full migration.
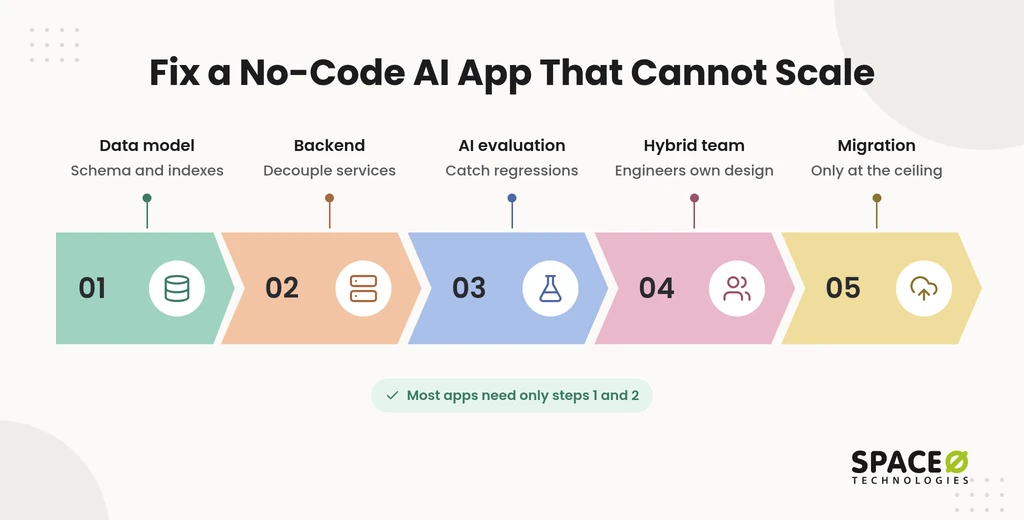
- Fix the data model first: Define the schema, relationships, indexes, and read and write paths. Normalize data to reduce redundancy and paginate large lists.
- Decouple the backend: Move heavy logic, auth, and data to PostgreSQL or Supabase with Node.js or Python services. Add Redis caching and background job queues.
- Add an evaluation suite for AI features: Test prompts against example cases and scenarios, the same way teams test an AI agent before launch, so one fix cannot silently break another.
- Use hybrid engineering: AI handles boilerplate, while engineers own architecture, security, and custom business logic. Plan the architecture with ChatGPT or Claude before any code is generated.
- Migrate when you hit the platform’s hard ceiling: Export what you can, then rebuild the core services outside the builder.
Moving past no-code is not a failure. Many teams treat low-code or custom development as the natural next step once a use case outgrows its platform, and they rebuild a no-code app one layer at a time. Threads on r/nocode often point to hybrid stacks, such as a WeWeb frontend with a Supabase or Xano backend.
What does a database fix look like in practice?
A typical database fix stops one query from firing on every keystroke. A search box built this way feels instant with ten testers. With many concurrent users, it multiplies database load with every letter typed.
The fix is straightforward. Debounce the input so it waits for a pause, batch related queries, and index the searched fields.
Can AI coding tools fix the problem alone?
No, AI tools speed up the work, but people still need to decide the architecture. Generated code mirrors the instructions it receives. Vibe coding without a planned data model repeats the same structural mistakes faster.
Use AI for repetitive code. Keep schema design, security rules, and business logic with engineers who review every change.
Move Your AI Calls Onto a Production Backend
Our generative AI integration services wire model calls into a backend with caching, queues, and evaluation. Traffic spikes then stop breaking the features your users already trust.
Patch, Hybridize, or Rebuild: Choosing Your Fix Path
Choose between patching inside the builder, decoupling the backend, or rebuilding core services. Your choice depends on what you must own and how regulated your data is. Compare the three paths on the factors that decide whether version two works. The “Best for” row ties each path to the stage of product it suits.
| Factor | Keep patching in the builder | Decouple the backend (hybrid architecture) | Rebuild core services with a partner |
|---|---|---|---|
| Best for | Early products still validating demand with light, stable usage | Apps with paying users, multi-tenant data, or audit obligations that must keep the front end live | Products whose builder blocks code export or whose logic breaks on every change |
| Code and IP ownership | Limited by the platform’s export terms | You own the backend code | Full code and intellectual property (IP) ownership |
| Control of the data model | Limited to what the builder exposes | Full control of schema and indexes | Designed upfront for growth |
| Production AI controls | Depends on platform features | Your team builds them | Personally identifiable information (PII) masking, hallucination testing, and human review |
| Compliance readiness | Depends on platform plan and caps | Achievable with in-house security expertise | Designed around your compliance requirements |
| Path to version two | Each fix risks breaking another feature | Workable if the frontend stays manageable | Built on the validated MVP, without starting over |
Whichever path you choose, the backend you land on needs the same production basics.
What a Production Backend for an AI App Needs
A production backend needs a tuned database, asynchronous AI handling, testing, observability, and access control. These are the controls that builders hide or skip. Each one closes a gap from the list above.
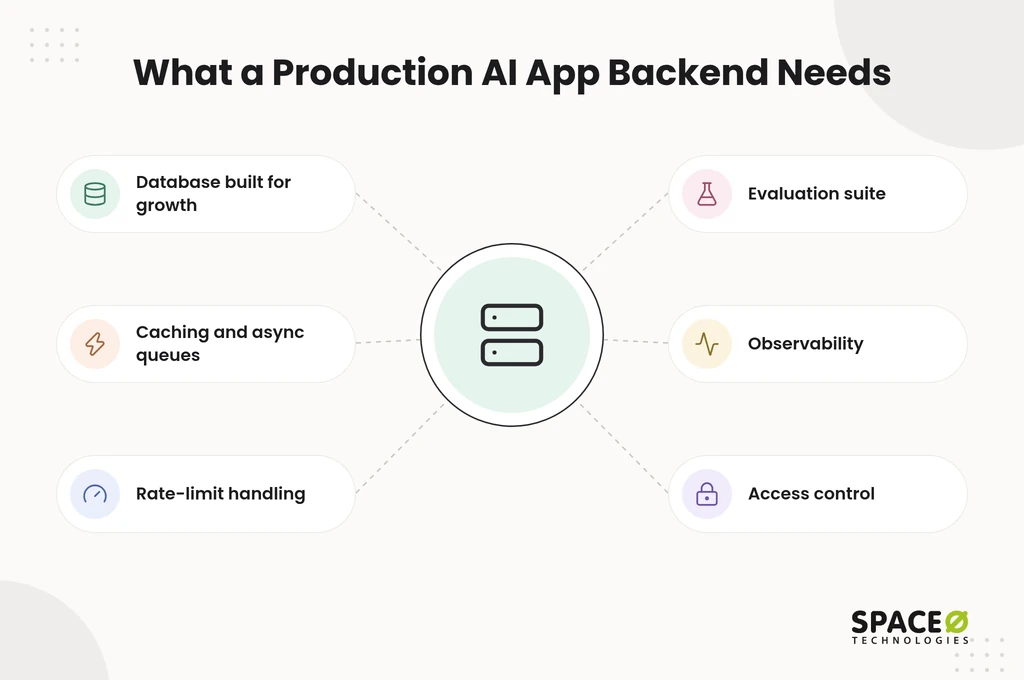
- A database built for growth: PostgreSQL or Supabase, with indexes, pagination, and connection pooling.
- Caching and async queues: Redis for repeat answers and background jobs for long AI tasks.
- Rate-limit handling: Retries, backoff, and smaller-model routing for simple requests.
- An evaluation suite: Checks for accuracy, hallucination rate, bias, latency, and cost before every release.
- Observability: Tracking of response times, error rates, throughput, and token cost per transaction, plus load testing before launches.
- Access control and tenant isolation: RBAC, isolated tenant data, and audit logs for regulated workflows.
Space-O Technologies tests AI features for hallucination and bias, with human review for high-stakes decisions. Budget for upkeep too. Annual AI maintenance typically costs 15% to 25% of build cost, per our AI development cost guide. Data preparation can consume 25% to 40% of the total project budget.
How Space-O Technologies Approaches a No-Code Scaling Rebuild
Space-O Technologies keeps your validated product and rebuilds only the layers that failed. Bring in a partner when your validated MVP needs architecture your team cannot build, such as when you must scale an AI MVP past its first users. That moment usually arrives with paying users, a compliance review, or an AI bill that outpaces revenue.
- Architecture planned for scale: We design multi-tenant architecture and continuous integration and continuous delivery (CI/CD) pipelines before the first new feature.
- Production AI experience: We have built AI-powered custom software and developed 300+ software solutions.
- Responsible AI by default: We never train on client data, we add PII masking, and we run hallucination and bias tests. People approve consequential decisions.
- Proof at scale: Since 2010, we have served 1,200+ clients with 140+ in-house developers. We built Glovo, which secured $1.2 billion in funding and passed 30 million downloads.
- Ownership and security: We sign a non-disclosure agreement (NDA) before every project. All source code, data, and IP transfer to you at completion.
- Flexible engagement and visibility: You choose Dedicated Team, Time & Material, Fixed Cost, or Staff Augmentation. A dedicated project manager (PM) sends daily updates.
What we need from you before a rebuild
Three facts let any engineering partner scope your fix accurately.
- Your platform and plan: Name the builder, your plan tier, and its code export terms.
- Where it breaks: Describe the failing symptom and the layer you suspect.
- Your current volume: Note active users or requests at peak.
Share those three facts with our engineering team. We will send a free, expert-reviewed estimate showing which layer to fix first.
Frequently Asked Questions
What does app scaling mean?
App scaling means the app keeps working as concurrent users, records, and requests grow. For an AI app, that includes query times, peak error rates, model-call latency, and token cost. If these worsen as usage rises, the app is not scaling. The cause is usually architecture, not user count.
Can I build an app without coding?
Yes, you can build and validate an app without coding, and no-code tools prove an idea quickly. The limits show up in production, with concurrent users, messy data, and rising LLM costs. Many validated products outgrow the architecture underneath them and then need the backend layers rebuilt.
What limits how far a no-code AI app can grow?
Code export terms and plan caps decide how far a no-code app grows. Check both before you commit. Keep the first version small and use it to validate demand before investing in architecture.
Why does AI struggle with code?
AI-generated code is only as good as its instructions. It ends up tuned for demos and happy paths, not production. Without a planned data model, prompt-generated code becomes tangled ‘spaghetti’ with no clear separation of concerns. Edge cases, network drops, and session failures then show up under real load.
Why does fixing one feature in an AI-generated app break another?
Prompt-generated code ties features together, so one change causes side effects elsewhere. If new features keep breaking old ones, the generated logic is your failing layer. In the short term, an evaluation suite that runs prompts against example cases catches regressions before release. If breakage continues, rebuild the core logic as structured backend services instead of patching with more prompts.
How do I stop my AI app’s model calls from failing during traffic spikes?
Move model calls behind a backend instead of calling them synchronously from the builder. Add Redis caching for repeat answers, job queues for long tasks, and retries with backoff. Route simple requests to smaller models to cut token cost.
How do I rebuild a validated no-code MVP without starting over?
Keep the interface that works and rebuild only the layer whose signals keep worsening. Fix the data model first, then decouple the backend to PostgreSQL or Supabase. Add an evaluation suite for AI features, and migrate core services last. Export what the platform allows and rebuild the rest outside the builder.
Why does a no-code app’s bill rise faster than its revenue as usage grows?
Your bill rises faster than revenue because builder tiers, usage fees, and per-token model costs all grow with usage. Every repeated question costs tokens again. Caching repeat requests and routing simple tasks to smaller models cut that cost.


 All our projects are secured by NDA


 4.8


